Tracing
A long run is thousands of tool calls across several agents. A trace turns what they left behind into one timeline you can actually look at.
It works whether or not a flow drove them — a trace of yesterday's claude session is one call away.
Collecting
/epics is every run of a flow in this directory, newest first. Put the cursor on the one you want, press enter to go into it, and export it gathers the trace and packs the run around it:
/home/you/code/.humanize/20260809T014455.212Z-9f21ab.epic.tar.gz · 812 kB · 3 sessions, 412 slicesThe trace itself goes into the run's own directory, as traces/export.trace.json, and into the archive beside it. Drag that file into ui.perfetto.dev, or open chrome://tracing and load it. It is a Chrome JSON trace, so anything that reads one will do.
A trace goes with the run it is a trace of. An epic already holds what happened, a link to every log each session was written to, and whatever the flow left behind, so the trace belongs there rather than in whatever directory you happened to be standing in. The default name is the UTC moment it was collected, so gathering one by hand twice keeps both rather than writing over the first; an output puts it somewhere else, its directory created if it is not there. The one export it writes has a name of its own — export.trace.json — so exporting a run twice leaves one trace, as it leaves one archive.
What is said under the list is where the archive landed, how big it came out and then what went into the trace inside it, and the transcript keeps the same line. A run that was profiled has a third count — 1 session, 10 slices, 3 programs — and one that was not stops at the slices.
From Python the same gathering is Hmz().epics.traced(epic), which is the call that row makes. What else the menu offers on a run is in the TUI reference.
Reading the trace
process   agent          builder · 4 sessions
  track     main ──────────────▶ ▓▓▓ ▓ ▓▓▓▓▓▓ ▓▓  ▓▓▓▓▓  ▓ ▓▓▓▓
  track     subagent · explore ▶      ▓▓▓▓▓▓▓▓▓▓▓
process   agent          reviewer · 2 sessions
track main ──────────────▶ ▓▓▓▓ ▓▓▓▓| In the trace | Is |
|---|---|
| a process | one agent and everything it drove, called <agent> · <n> sessions — or, for a profiled run, one program it ran, called <program> · <pid> |
| a track | one row of that agent's sessions: main for the ones somebody started, subagent for what a turn reached for. Sessions of one agent that never run at the same time share a track; root sessions and sub-agents stay apart. Or one thread of that program. |
| a slice | one action — a tool call, a message, or waiting for reasoning |
A row of sub-agents that were all started as the same kind is named after that kind — subagent · explore rather than five names run together — and a sub-agent that started one of its own is subagent 2. A second row at the same depth is #2 after the name, and actions that do overlap inside a row spill into lanes of their own, ~2 after it.
Click a slice and its arguments are there: the prompt, the reasoning, the tool input, the tool output. As much as the backend wrote down.
The document's otherData says what was asked for and what was collected — the workspace, the sessions named, the agents and backends found, how many sessions, slices and tracks there are, and the first and last moment in it. A profiled run adds programs, how many of them were drawn; a trace of sessions alone does not carry the key at all.
What counts as one agent
An agent is one configuration — a backend at a model at an effort — together with every sub-agent it started. So a Ralph loop of a hundred one-shot sessions reads as one agent rather than a hundred, and a sub-agent belongs to the agent of the session that started it, whatever it ran at itself.
That default is a guess, and it has a blind spot: two agents at the same configuration are indistinguishable, because the backends log a session under an id and never say whose it was. An actor and its reviewer at one model and one effort would read as one agent.
A run that drove the sessions itself knows better. A trace of a run reads that off the run's own record, so rlar traces as actor and reviewer without being told anything. Driving agents by hand, say so yourself:
collect(agents={a.id: a.opened for a in (actor, reviewer)})Sessions nobody claims are read as the configuration they ran at.
Epics
Every run of a flow is one epic, written as it happens, and an epic is a directory:
~/.humanize/epics/<workspace>/<datetime>-<hex>/
    epic.jsonl                      what happened, a line at a time
    epic.<flow>_<hex>.jsonl         the same, for one flow the run called
    state.json                      what a flow that can be picked up again left behind
    profile.jsonl                   the programs it ran, for a run that was profiled
    sessions/<session>/…            a link per file the backend logged that session to
    traces/export.trace.json        the trace exporting the run gathers, replaced each time
    traces/<datetime>.trace.json    one gathered by hand afterwards, which keeps every one
<workspace> is the absolute path with everything that is not a letter or a digit flattened to -, the way the backends flatten a workspace into the folder they log it under. <hex> is six characters, because two flows may be started in one millisecond and neither is the other's run.
epic.jsonl is JSON lines, one line per thing that happened to the run, appended and flushed as it goes — a run that died is a run whose epic still says what it got to.
event | Written | Carries |
|---|---|---|
began | when the flow starts | flow, task, workspace, whether the flow is resumable, the run it was picked_up from where there was one, and one entry per agent with its agent id, backend, model, effort, permission, provider, goals and whether it was the person at the prompt |
opened | each time an agent opens a session | agent, backend, provider, session, the name the run gives it and where its links are |
called | when the flow calls another flow | flow, task, and the epic — the record that call was written to |
returned | when that call returns, however it ended | flow and the same epic |
ended | when the flow stops | how: done, failed, or stopped |
sessions/<session>/ is a link per file that session was logged to, named for whose session it was, what took its turns, which account they ran as and what the backend called it — builder-claude@work-0a1b2c3d, and @local where the turns ran as the account this machine is already signed into rather than one humanize keeps. They are there to be read: humanize itself reads and writes every log where the backend keeps it.
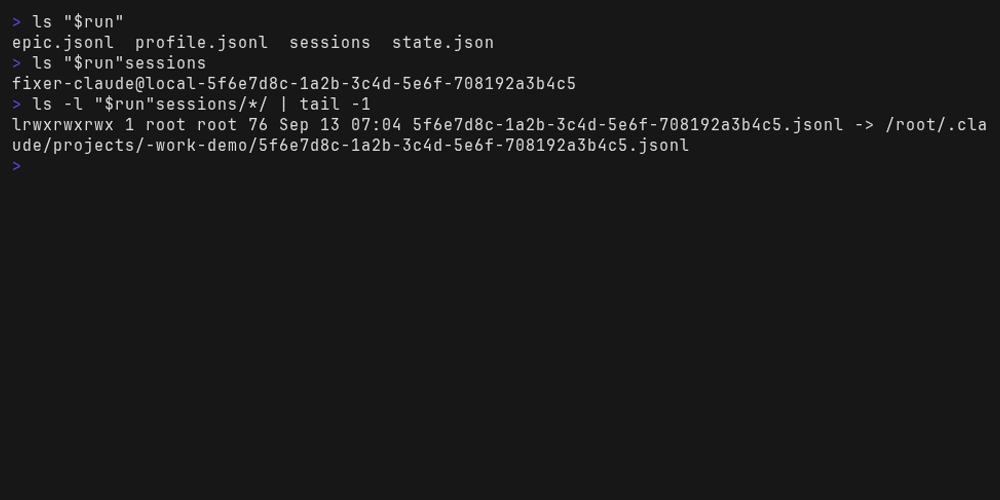
The links are made when the session opens and made again when the run ends, since a backend goes on writing a log after the turn that opened it and a sub-agent's transcript appears whenever that sub-agent ran. A filesystem that will not make one is a run without links rather than a run that stops.
It is not a transcript. The backend's own log is the turn-by-turn record, and an epic is not a second copy of it. What is kept here is the shape of the run — enough to gather a trace afterwards out of the ids alone.
An epic covers one run. It closes when the flow finishes, fails or is interrupted, and a closed epic is never reopened: running the flow again is another run, with sessions of its own, and so another epic.
That is what state.json, resumable and picked_up are for. A flow that says @flow(resumable=True) takes a state dict as its last argument, and what it writes there is state.json in the epic of the run that wrote it, keyed by the name the flow was run under. Running that flow again here carries on from the last run of it that left anything — into an epic of its own, whose began line says which run it was picked_up from, so a week of stops and starts reads as the week it was. /epics picks a named run up: enter goes into a run and offers resume this run, which is asked of the flow rather than of the run, a flow being a file that may have been rewritten since. See Picking a run up and a flow that can be picked up.
An agent stopped by hand makes the run stopped rather than failed, whatever the turn under way made of it — so a run you ended is written down as one you ended.
from hmz.runtime.epic import epics, opened

for epic in epics():                   # this workspace, oldest first
    print(epic, opened(epic))          # {"actor": ["0a1b…", "5f6e…"], "reviewer": [...]}
Records of called flows
A flow may call another, and a called flow opens sessions, keeps state and calls flows of its own. So every call gets a record of its own beside the run's — epic.inner_0a1b2c.jsonl for a call of inner — and the record of whatever called it says called and returned with the filename in epic. Named for this call rather than for the flow: one flow called twice is two runs of it, each with its own sessions.
A record of a called flow holds the same events as the run's own. Its began also carries under, the record that called it, so a flow that called a flow that called a flow reads back as the shape it ran in. Its ended says how the call ended — a call that raised is failed inside a run that may still be done.
Records nest. A call made from inside a called flow is written under that flow's record, so a recursion five levels deep with two branches at every level reads back as the tree it ran as rather than as thirty-one things one run did. hmz.runtime.epic.tree reads it that way:
from hmz.runtime.epic import tree

for one in tree(epic):                 # the calls the run itself made
    print(one.flow, one.record, len(one.calls))   # and what each of those called in turn
Two calls that ran at once are two of these, with began and ended that overlap and a record apiece — which is what tells them from one another, the flow's name being the same name.
It is still one run and still one directory: a called flow is part of the run that called it, not another run. hmz.runtime.epic.sessions reads every record, so every session of a run is one list however many flows it took, each saying which flow opened it and which record — which is to say which call of that flow — it was opened in.
A session the flow branched also says parent, the id of the conversation it was forked from. The backend's own log cannot: it shows a session that opened on an agent already knowing things, and only the run knows where it knew them from.
Profiling a run
An agent's turn is mostly other programs. It runs the tests, it builds the thing, it greps the repository — and none of that is in a backend's log, which records the tool call rather than the process. So a workspace may ask for its runs to be profiled as well as traced, on the second page of /settings:
3. profile on profile the programs a run here startsWhile the flow runs, the programs underneath it are sampled — what each was, what started it, and how long it took — into profile.jsonl in that run's own epic. Collecting the run puts them in the same document as its sessions, drawn the same way: a process is a program and a track is one of its threads, exactly as a process is an agent and a track is a row of that agent's sessions.
That is the point of one document rather than two. An agent's timeline and a profiler's timeline at one scale means what was this run doing at 09:41 has one answer:
process   agent          builder · 4 sessions
  track     main ──────▶ ▓▓▓ ▓ ▓▓▓▓▓▓ ▓▓  ▓▓▓▓▓  ▓ ▓▓▓▓▓▓▓▓▓▓
process   program        pytest · 41207
  track     main ──────▶       ▓▓▓▓▓▓▓▓▓▓
It is sampled rather than intercepted: nothing goes between an agent and what it runs. A program that lived for thirty milliseconds may be missed, and a machine whose processes cannot be read is a run with no profile rather than a run that stops.
Where the trajectories come from
The backends' own home directories, which humanize only reads:
| Backend | Environment variable | Default |
|---|---|---|
| Claude Code | CLAUDE_CONFIG_DIR | ~/.claude |
| Codex | CODEX_HOME | ~/.codex |
| DeepSeek Harness | DSH_HOME | ~/.dsh |
| Kimi Code | KIMI_CODE_HOME | ~/.kimi-code |
Those four, and no others. opencode, mimocode and Antigravity keep a session in a database rather than in a log file, and nothing here reads pi's, Grok Build's, Qwen Code's or ZCode's own logs yet, so there is nothing to gather for those: a run of theirs is watched as it happens rather than collected after.
A home that does not exist is skipped rather than being an error, so collecting on a machine with only one backend installed works — and so is a backend humanize has no reader for, whose home being there changes nothing.
What one trace holds
A trace is of a run, and holds the sessions that run opened and no others:
from hmz.sdk import Hmz

runs = Hmz().epics                            # or Hmz("~/code/other").epics, for another
last = runs.all()[-1]                         # the last run of this workspace
runs.traced(last)                             # its own sessions, into its own traces/
runs.traced(last, start="3 days ago")         # and only what it did since
The run wrote down which sessions its agents opened, and those ids are what the trace is gathered by — so a directory run in fifty times has fifty traces to collect and none of them holds another's work. A run that opened nothing is a trace of nothing rather than a trace of whatever else the directory has seen. Asked for by id and not by directory, which is why a flow that ran on a machine of its own — working in a mirror, logged under a path this workspace has never heard of — is in its own trace all the same.
A run is named by the directory it is written in — what all() lists, oldest first, and what /epics draws at the top once you are inside the run. There is no name to spell and no leading part of one to match, because a run is picked out of the runs there are before there is anything to trace.
Or of a directory, whoever opened its sessions, which is how an afternoon at a coding agent that no flow ever drove is read back:
Hmz().epics.trace()                                    # every session of this workspace
Hmz("~/code/other").epics.trace()                      # every session of another
Hmz().epics.trace(sessions="0a1b2c3d,5f6e")            # two sessions, wherever they ran
Hmz("~/code/other").epics.trace(sessions="0a1b2c3d") # that session, only if it ran there- Naming sessions alone collects them wherever they were recorded.
- Naming a workspace with them keeps only the named sessions recorded there.
- Naming no sessions at all collects the workspace, whichever run opened what is in it and whether any did.
A session is named by its whole id, by the key the trace shows it under, or by a leading part of either — and the sub-agents it started come with it.
Neither of these is a trace of any run, so neither has a run to be filed in: trace hands the document back and writes a file only where an output says to. A run and a directory are two calls rather than two arguments to one, so there is nothing to ask for at once and nothing to quietly win. And neither is offered in the interface: /epics is a list of runs, and a trace of what is not one has nothing there to be reached from.
A workspace nothing has ever been run in has no run to trace and nothing in /epics to trace it from. What the backends logged there is still a trace away.
start and end take anything dateparser understands and cut records outside the range, either way. A time that cannot be read raises ValueError. An output wins over where a trace would otherwise land.
From Python
Hmz().epics is the way in — traced for a run, trace for sessions asked for by id — and one call is underneath both of them:
from hmz.runtime.tracing import collect

document = collect(
    "~/code/myproject",             # or None, for sessions asked for by id alone
    sessions=["0a1b2c3d"],          # a string or an iterable of ids
    agents={"actor": [...]},        # what each agent opened
    output="trace.json",            # omit and nothing is written
    start="3 days ago",
    end=None,
    profile=epic / "profile.jsonl",  # the programs that run started, if it was profiled
)
Returns the trace document. Writes a file only when output is given, so gathering one to read in the process that asked for it leaves nothing behind.
sessions unset is every session of the workspace; an empty sessions is no session at all, which is what the trace of a run that opened none holds. Naming sessions is a filter, and naming none of them is not the same as naming all of them. Collecting a run's own trace is that call with the ids the epic wrote down and no workspace — which is what traced and /epics both do.
Raises ValueError if a time cannot be read or a named session is empty; the interface says either under the list rather than shutting the menu on it.
Watching a run instead
A trace is for after. While a run is going, the interface's /monitor shows the same shape live: who is working, every handover between agents with how often it happened, and what each model has cost — in tokens, in money, and the rate it is costing it at.
That is read from the turns going past and from the logs the backends write as they go — never by asking the flow, which is a Python file that may branch any way it likes. See TUI.